Work · Documents
document-extractor.
A PDF goes in. Structured fields come out, each one pointing back to the words on the page.
The problem
Retyping the same nine fields, hundreds of times a week.
Imagine a finance operations desk that closes the week by retyping 400 invoices. Each one is a PDF: a number, a due date, a total, two company names. Someone opens the file, finds those nine fields, and keys them into a spreadsheet. The work is careful and slow, and a transposed digit is easy to miss until a payment comes back.
The useful result is not a model that can “read PDFs.” It is a list of fields a person can audit, because every value still knows the place on the page it came from.
What we built
A pipeline that returns a claim, and the exhibit attached to it.
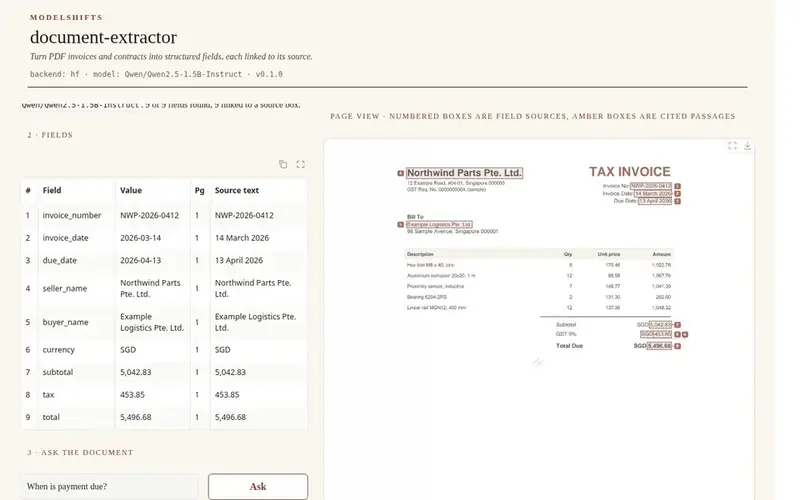
The pipeline is five steps, and a sixth if you ask a question. A PDF or a scan is read into words with coordinates (Florence-2 for scanned pages). A YAML schema lists the fields you want. Each returned value is matched back to the printed words on the page, and comes back as JSON with its page, bounding box and source text. Ask a question and a retriever — bge-m3, or BM25 — picks passages; the model answers with citations.
Think of each field as a claim, and the bounding box as the exhibit attached to it. The backend can be a hosted API or open models on your own machine; the rest of the pipeline stays the same.

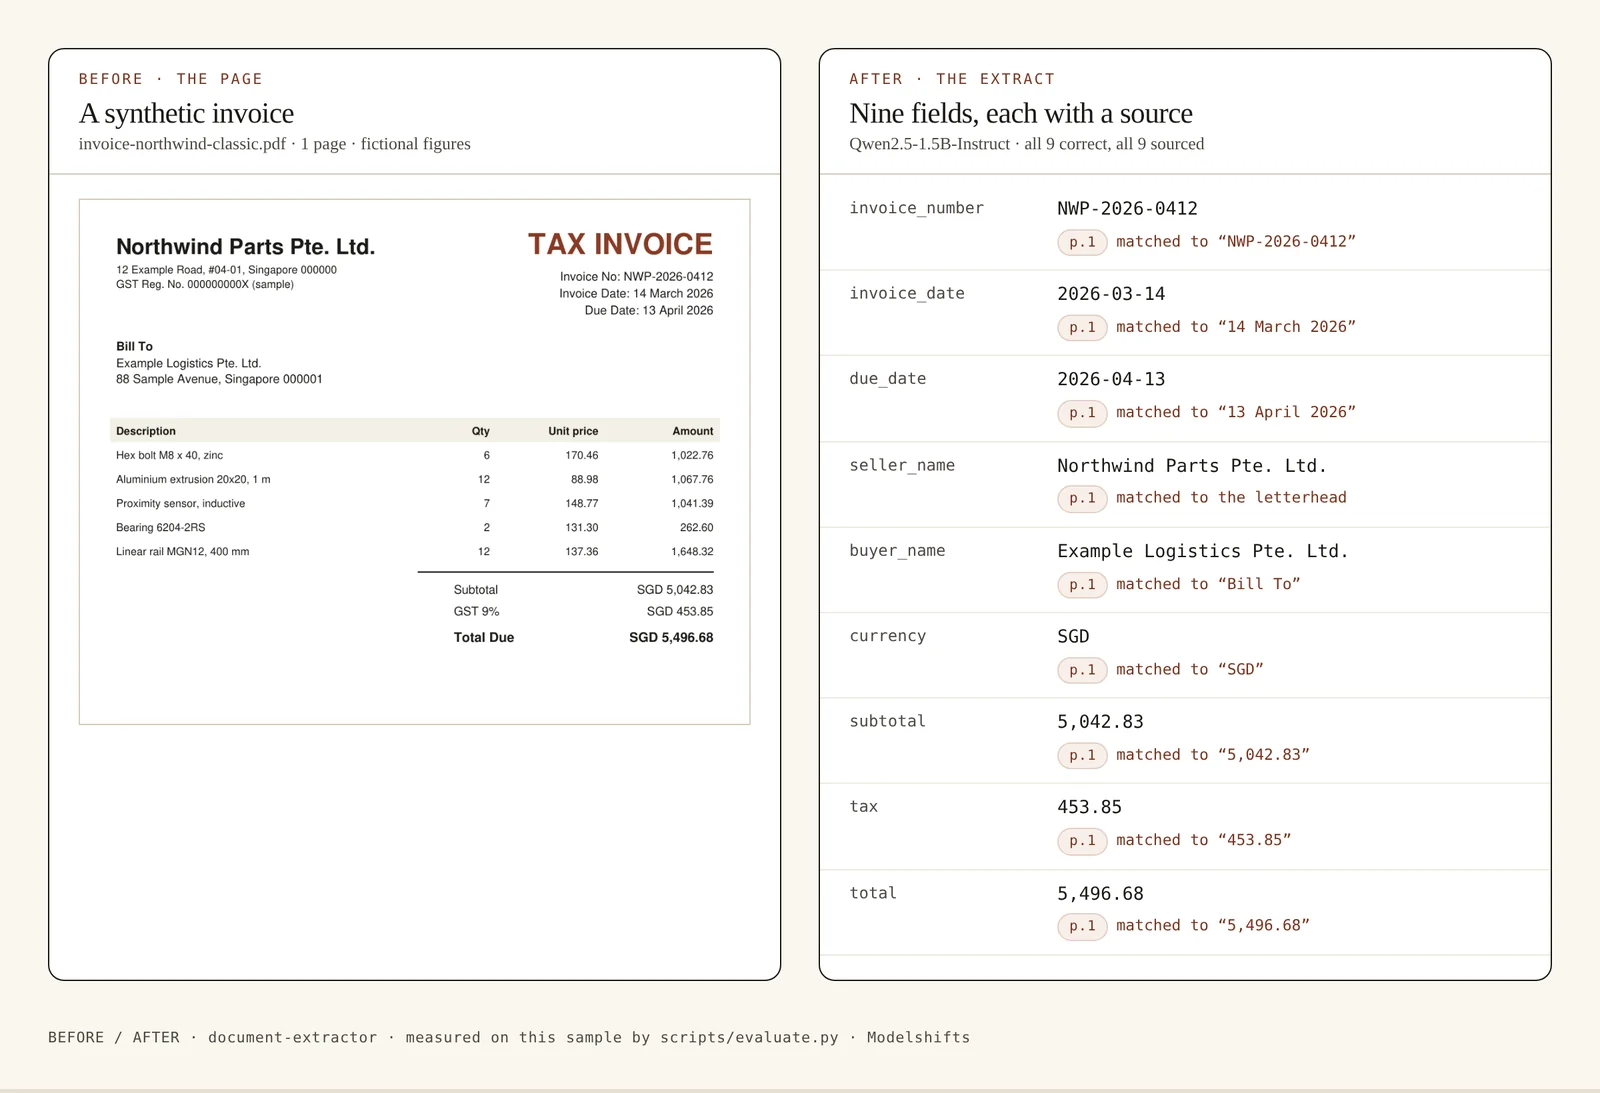
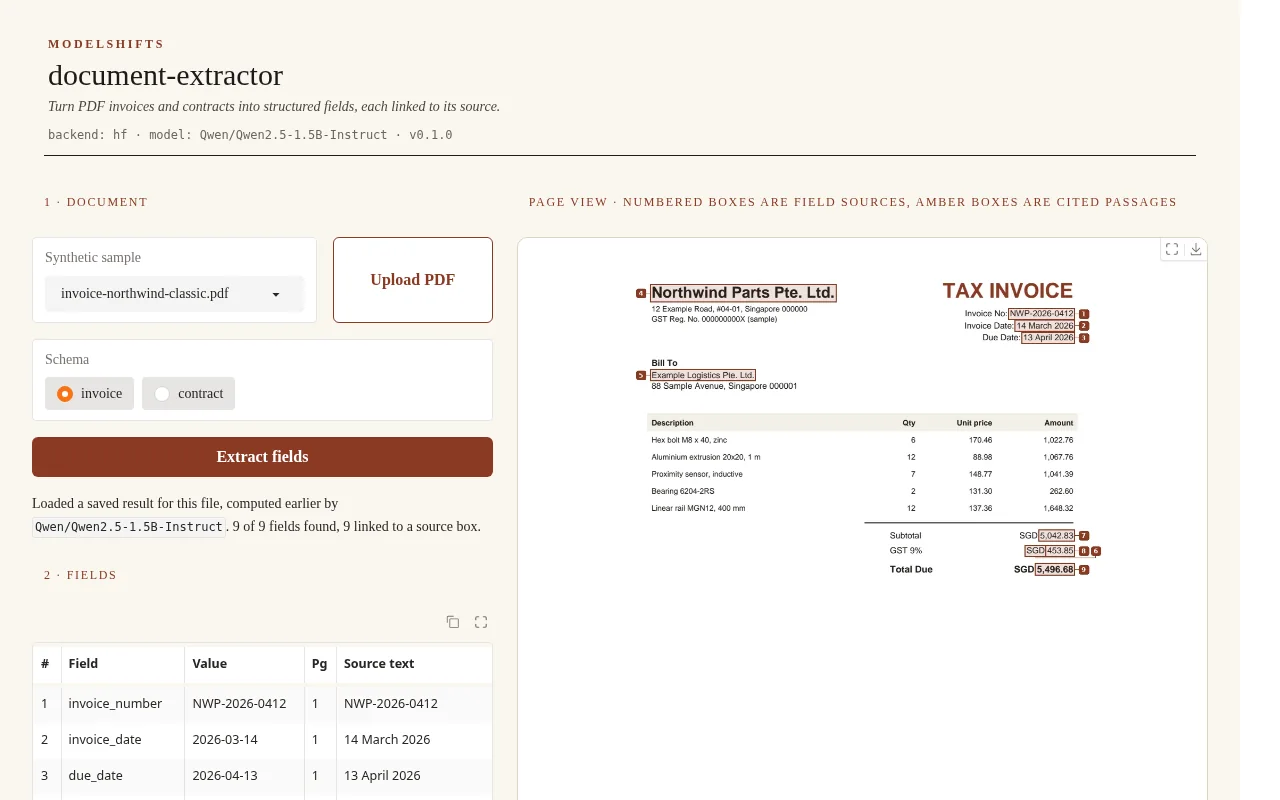
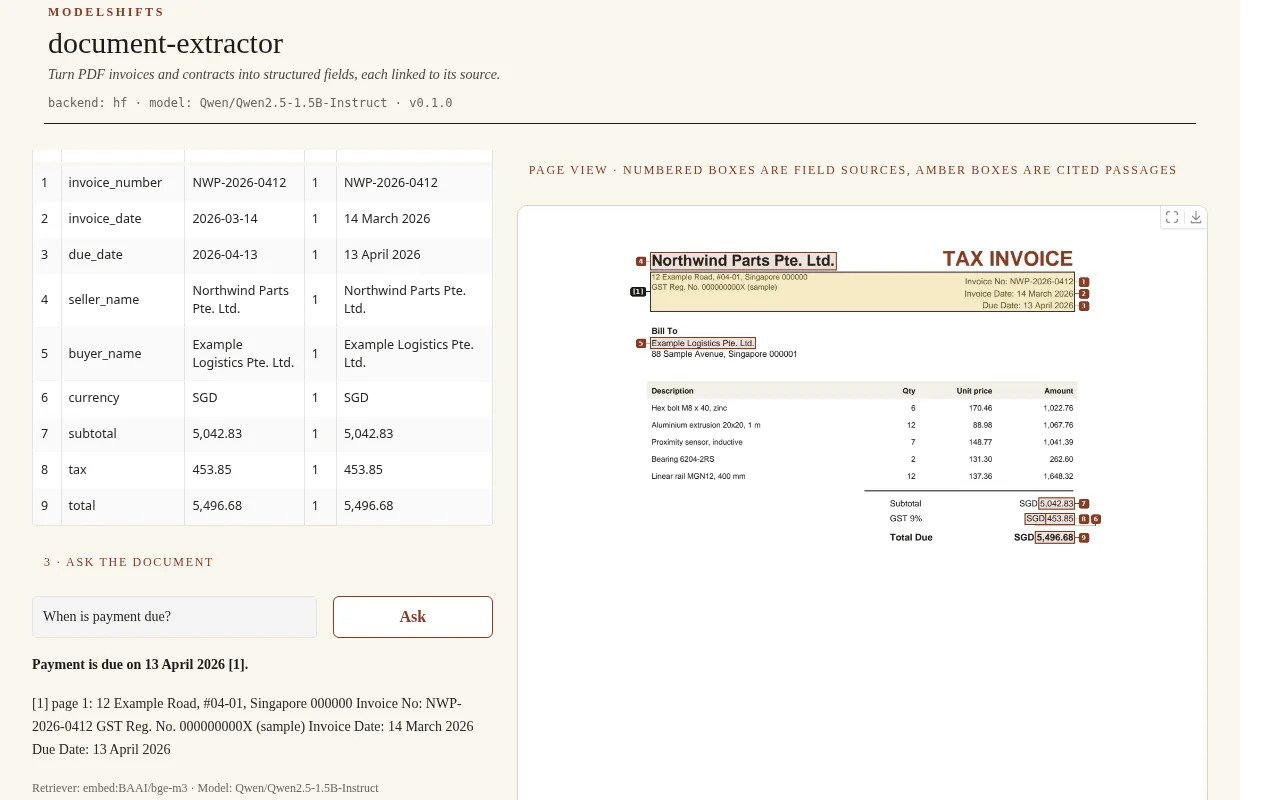
A total without a source is a rumour. A total with a bounding box is a claim you can audit — from 5,496.68 back to the printed “SGD 5,496.68” on the page, and reject it if the box is wrong. That is the difference between an extract you retype to be safe, and an extract you can actually use.
Results
60 of 61 fields correct, every correct value sourced.
-
60 / 61
Fields correct · 98%
-
60 / 60
Correct values sourced
-
9–22 s
Per document
On seven PDFs — four invoice layouts, two contracts, and one image-only scan — the Hugging Face backend with Qwen2.5-1.5B-Instruct got 60 of 61 fields correct (98%). Every correct value also carried a source box whose text matches the value (60/60).
The one miss is an OCR slip on the scanned invoice: buyer_name came back as Northwind Parts Pte., Ltd. (an extra comma) instead of Northwind Parts Pte. Ltd.
| Sample | Correct | Sourced | Time (s) | Notes |
|---|---|---|---|---|
contract-master-services.pdf | 8/8 | 8/8 | 18.7 | — |
contract-supply.pdf | 8/8 | 8/8 | 9.0 | — |
invoice-acme-scanned.pdf | 8/9 | 8/8 | 22.1 | buyer_name: extra OCR comma |
invoice-demo-freight-compact.pdf | 9/9 | 9/9 | 10.5 | — |
invoice-example-logistics-banner.pdf | 9/9 | 9/9 | 9.7 | — |
invoice-northwind-classic.pdf | 9/9 | 9/9 | 10.9 | — |
invoice-placeholder-two-page.pdf | 9/9 | 9/9 | 13.6 | — |
| All | 60/61 (98%) | 60/60 | 9.0–22.1 |
Methodology. Seven PDFs (four invoice layouts, two contracts, one image-only scan), 61 fields in total. A field counts as correct when the typed value matches the ground truth in samples/*.truth.json (strings compared case-insensitively, extra spaces and trailing punctuation ignored; numbers within 0.005). “Sourced” counts correct values that also carry a source box whose text matches the value. Hugging Face backend, Qwen2.5-1.5B-Instruct, Florence-2 for the scanned page, 12 November 2026. Wall-clock for all seven samples was 96 seconds, including model load. Per-document times were 9.0–22.1 seconds. The raw table is in docs/eval.md. The script is scripts/evaluate.py; the samples are in samples/.
The API backend against a local llama.cpp server (Qwen2.5-1.5B-Instruct, Q4_K_M) got 52 of 61 fields correct: all 52 fields on the six text-layer PDFs, in 3.9–12.1 seconds each. The scanned invoice is scored 0/9 there, because that backend has no OCR unless a vision model is configured.
Run it yourself
Three commands, then the demo.
git clone https://github.com/ModelShifts/document-extractor
cd document-extractor && python -m venv .venv && source .venv/bin/activate
pip install -e ".[hf,demo]" && document-extractor serve
On a CPU-only machine, install the CPU build of PyTorch first and set MS_HF_MODEL=Qwen/Qwen2.5-1.5B-Instruct. Python 3.11 or newer.